SYG Consulting · Agentic simulation

Compare policy options across thousands of simulated futures.

Your experts design a world of language-model agents. Each option runs against matched disruptive events. You receive a distribution of futures, a traceable record, and a method note.

SYG Consulting mark, reversed

Prediction and simulation are different claims

A prediction says what will happen. A simulation says what tends to happen, and how often, across many runs of one design.

Prediction versus simulation: one narrative line against a fan of trajectoriesPREDICTION VERSUS SIMULATIONOne narrative, or a distribution of futuresNarrative assessmentone trajectory, its assumptions implicittimestatethe expected coursea shock that was not written inAgentic simulationhundreds of trajectories per option, shocks sampledtimestateshockshockThe simulation returns frequencies across runs, conditional probabilities given an event sequence, and tipping points.It does not resolve whether the generative model of the world is correct; it improves reliability, not validity.Conceptual. No run is a forecast; findings hold under the assumptions of the simulation and are stated as such.

How a simulation works

  1. Frame

    Several options, many actors, frequent shocks.

  2. Design

    Your experts review every entity; the design is frozen.

  3. Build

    Agent prompts are generated from the frozen design.

  4. Pilot

    Staged runs, then a pre-registered bias battery.

  5. Calibrate

    Corrections are verified and cleared by your experts.

  6. Run

    Each option runs thousands of times against matched events.

  7. Read

    Findings are frequencies; every claim traces to its source.

Engagement lifecycle with four expert gatesENGAGEMENT LIFECYCLEEight phases, four expert gates0FramingQuestion-class fit, alternatives, horizon, configuration, deliverables1DesignPre-load, silent review, workshop, change register, decisions fileGATE · DESIGN FROZENValidator passes; hash computed; design confirmation signed — expert group2BuildEngine adapted to the pack; prompts generated and checked for parity3PilotStaged runs with automatic gates and a spend ceiling; bias batteryGATE · PILOT PASSEDMechanics reliable; plausibility reviewed; battery responded to — design owner and experts4Client confirmationDesign-and-pilot report, decision form, player and event book, record5Corrections and verificationContent validator first, then referee and ensemble; four-run verificationGATE · CALIBRATION CLEAREDVerification gates pass, including mobility; anchors reviewed — production does not start before this6ProductionHundreds to thousands of runs per option; extended where not convergedGATE · VALIDATION REVIEWSampled production trajectories read by experts; residual bias measured and disclosed7HandoverDatabase, record, frozen pack, method note, replication kit; 90-day supportBuild does not start until the design is frozen; production does not start until calibration clears. Experts re-confirmed at every gate.
  • Hundredsof actors, each with the positions, red lines, and relationships your experts set
  • As many optionsas the question needs, always with a status quo
  • Hundredsof shocks, organic and scripted
  • Tens of thousandsof scenarios, from which the big narratives emerge
  • A Monte Carloprobability layer on top
  • Every claimtraceable to run, decision, and source

Findings are distributions across simulated futures, read under the assumptions of the design. No run is a forecast.

Six capability tiles: actors, options, shocks, scenarios, narratives as frequencies, probability layerWHAT A SIMULATION CAN HOLDFrom actors to probabilitiesHundredsof actorsfactions inside,one agent eachAs many optionsas neededalways with astatus-quo armHundredsof shocksorganic andscripted eventsTens ofthousands ofscenarioshundreds of runsper optionBig narrativesread asfrequencieswhat recurs,and how oftenMonte Carloprobabilitylayerconditional odds,tipping pointsCapability ranges, not fixed counts. Scale improves reliability, not validity; every run is one draw, never a forecast.
Figure 1.Capability ranges, not fixed counts.

How bias is tackled

Each source of bias maps to a design response; a pre-registered battery measures whether it worked.

Bias and the black box cannot be removed entirely. They can be measured, reduced, and disclosed, and that is what the design does.

Seven sources of bias mapped to design responsesHOW BIAS IS TACKLEDSource of bias, and the design responseMeasured before results are read, re-run after every correctionSOURCE OF BIASDESIGN RESPONSEModel priors on the domainGrounding in documented sources and historical anchorsEscalation propensityRestraint written into every brief as a costed option; propensitymeasured and disclosedPersona draftingExpert review with a diverse panel; disagreement registerPrompt framing and formatOne shared template; every rewrite measured on fixed seedsModel-strength asymmetryUniform-model test on pre-registered metricsState-transition rulesReferee with inertia, decay and expert-set boundsCultural and linguistic normalizationDisclosed; heavier expert calibrationBias and the black box are reduced to a minimum and disclosed;removing them entirely is not possible.The last source (dashed) is addressed by disclosure and calibration, not by a mechanism. Residual bias is stated in the method note.

Models, tested before they are selected

Candidate models are compared on pre-registered metrics before the fleet is set. Versions are pinned and recorded in every call.

Model selection: candidates, experiments on pre-registered metrics, selected fleet by tierMODEL SELECTIONModels tested before they are selectedCANDIDATE MODELSseveral vendor familiesVendor family AVendor family BVendor family CVendor family DVendor family EEXPERIMENTSsame design, fixed seedsPre-registered metricsPosture entropyRestraint shareText integritySchema validityInter-judge agreementEvery model runs the same battery.SELECTED FLEETby tier · versions pinned per batchTop tierprincipal decision nodesMid tiersub-factions, secondary actorsBase tierbackground, opinion proxiesPinned model, or a visible failure.testedselectedCross-vendor adjudication ensemblea diagnostic on contextual judgments: two or three vendor families judge the same case;disagreement is measured and routed to experts, not averaged awaySelection is experiment-based and repeated when a model version changes; the fleet in use is stated in the method note.

Humans review and decide

Your experts design the world and decide at four gates. Their splits are recorded, never averaged, and define the sensitivity sweep.

Four human-in-the-loop configurationsHUMAN IN THE LOOPFour configurations, presented as an adaptationless human intervention between gatesmoreMODE 0Fully autonomousAgents and adjudicationrun without interventionbetween gates.Production batchesMODE 1Expert gatesDesign freeze, pilotreview, calibrationsign-off, validation review.The defaultMODE 2Adjudicator overrideExperts rule on flaggedensemble disagreements;rulings become designchanges.Used in calibrationMODE 3Human on the boardOne faction played bya person against a fullagent board.Least evidencedBeyond the gates, humans are decisive at three points: plausibility bounds, decay rates and fatigue modelsare signed by experts; red-line flags are routed for expert reading; the outcomequestions are the experts' to define.No established typology exists for this application; no controlled study seats humans and language-model agents together.

Who it is for

  • Government, defense, and policy

    Courses of action compared under frequent shocks.

  • Corporate strategy

    Strategies tested against the same disruptions.

  • Financial and macro analysis

    Publics and institutions under a policy regime.

Background papers

  • The evidence base for agentic simulation

    What the literature supports.

    Read the paper →
  • Method: design, validation, and bias control

    The method as built and tested.

    Read the paper →
  • Agentic digital twins: a systematic review

    The field and its open validation problem.

    Read the paper →

About SYG
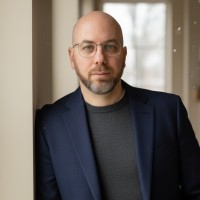
Shay Hershkovitz, PhD

Shay Hershkovitz, PhD Founder and Principal, SYG Consulting. Adjunct at Georgetown University and RAND. About Shay and SYG

Bring us a question with more than one answer.

A short conversation tells whether your question fits. If not, we say so.